
ASRock Intel Arc Pro B60 Creator
3.9Editor score
Twenty-four gigabytes GDDR6 memory
Xe2-HPG architecture for AI
Optimized for Linux multi-GPU
This guide compares the top ten GPUs for running large language models locally, focusing on VRAM, architecture, and performance for AI inference and fine-tuning
Selecting the right graphics processing unit is critical for anyone looking to run large language models locally. The ideal GPU must balance memory capacity with computational throughput to ensure smooth inference and efficient fine-tuning processes without relying on external cloud services.
We have evaluated ten distinct graphics cards ranging from consumer gaming models to professional workstation solutions. Each product was assessed based on memory size, architecture generation, cooling efficiency, and specific features that enhance AI workflow performance in localized environments.
Every pick highlights specific strengths for different user needs such as budget constraints or enterprise scale requirements. Keep in mind that availability and stock levels fluctuate frequently so you should verify current details before making a final purchasing decision for your setup.
3.9Editor score
4.6Editor score

This side-by-side comparison table helps you quickly identify the key specifications of each graphics card to determine which one fits your specific large language model deployment requirements best.


This graphics card stands out as a top choice for running large language models locally due to its powerful Blackwell architecture and sixteen gigabytes of fast GDDR7 memory which supports complex AI inference tasks efficiently.
We may earn a commission when you buy through this link, at no additional cost to you.
The integrated WINDFORCE cooling system ensures that the card remains cool even under sustained workloads typical of fine-tuning or batch processing tasks. Its PCIe 5.0 interface provides the bandwidth necessary to feed data to the GPU without bottlenecks.
Users should be aware that this card requires a robust power supply and adequate case clearance due to its size and thermal demands. However the performance gains in AI workloads justify the hardware requirements for serious local development.
Developers looking for a reliable balance between consumer availability and professional grade performance will find this model to be an excellent investment for their workstation or home server setup.
The GDDR7 memory interface significantly reduces latency when loading model weights which is crucial for faster iteration times during development.
Advanced cooling technology prevents thermal throttling allowing the GPU to maintain peak frequencies throughout long training or inference sessions.
We may earn a commission when you buy through this link, at no additional cost to you.
This workstation GPU offers an impressive twenty-four gigabytes of VRAM which is a significant advantage for running larger models without quantization. Its cost effective pricing makes it accessible for enthusiasts and small teams starting their local AI journey.
We may earn a commission when you buy through this link, at no additional cost to you.
The card is optimized for Linux multi-GPU deployments which allows for scalable performance as your needs grow. It features a single 8-pin power connector simplifying installation in systems with standard power supplies compared to newer high-wattage models.
While the software ecosystem is still maturing compared to NVIDIA the raw memory capacity and PCIe 5.0 support make it a viable option for inference workloads. The blower style cooling is efficient for multi-card setups but may generate more noise.
Budget conscious users who prioritize memory size over raw single card speed will appreciate the value proposition here. It serves well as a secondary card or for specific tasks where memory capacity is the primary bottleneck.
The large VRAM pool allows for running bigger context windows or multiple smaller models simultaneously without offloading to system RAM.
Optimized support for multi-GPU setups enables you to add more units later to increase total system memory for enterprise workloads.
We may earn a commission when you buy through this link, at no additional cost to you.
This professional card delivers thirty-two gigabytes of memory making it capable of hosting very large language models entirely in VRAM. The RDNA 4 architecture includes dedicated accelerators designed to speed up AI inference and content creation tasks.
We may earn a commission when you buy through this link, at no additional cost to you.
Designed for workstation environments it features a professional blower cooling solution that exhausts heat directly out of the chassis. This design is ideal for tight multi-GPU configurations where airflow management is critical for system stability and longevity.
The die-cast metal shroud and backplate provide structural integrity ensuring the card can handle 24/7 operation in server or studio settings. ISV certification ensures compatibility with professional software suites used in engineering and design industries.
Professionals requiring maximum local memory capacity will find this card to be a strong competitor to high-end NVIDIA solutions. It represents a significant step forward for AMD in the professional AI acceleration market.
Built-in AI accelerators improve throughput for common machine learning operations compared to general purpose shader cores alone.
The compact two-slot design allows for high density GPU placement in server racks without excessive power consumption.
We may earn a commission when you buy through this link, at no additional cost to you.
This model offers sixteen gigabytes of memory at a competitive price point making it accessible for mid-range AI workloads. The server-grade thermal conductive gel helps maintain consistent performance during extended periods of high utilization.
We may earn a commission when you buy through this link, at no additional cost to you.
The WINDFORCE cooling system provides reliable temperature management ensuring the GPU stays within safe operating limits. Its PCIe 5.0 interface ensures it is ready for future motherboard upgrades and bandwidth demands.
While it may not have the massive memory of higher end cards it still handles smaller models and quantized versions of larger ones effectively. The high user rating indicates satisfaction with its reliability and thermal noise levels.
Users looking for a balance between cost and performance for entry to mid-level inference tasks should consider this card. It provides a solid foundation for learning and development without breaking the budget.
High quality thermal materials help dissipate heat effectively allowing for sustained clock speeds without throttling under load.
Support for the latest PCIe standard ensures the card will remain relevant as system architectures evolve over time.
We may earn a commission when you buy through this link, at no additional cost to you.
This card is engineered for durability with military-grade components and protective PCB coating to resist environmental factors. It utilizes phase-change thermal pads that provide superior heat transfer compared to traditional thermal paste for longevity.
We may earn a commission when you buy through this link, at no additional cost to you.
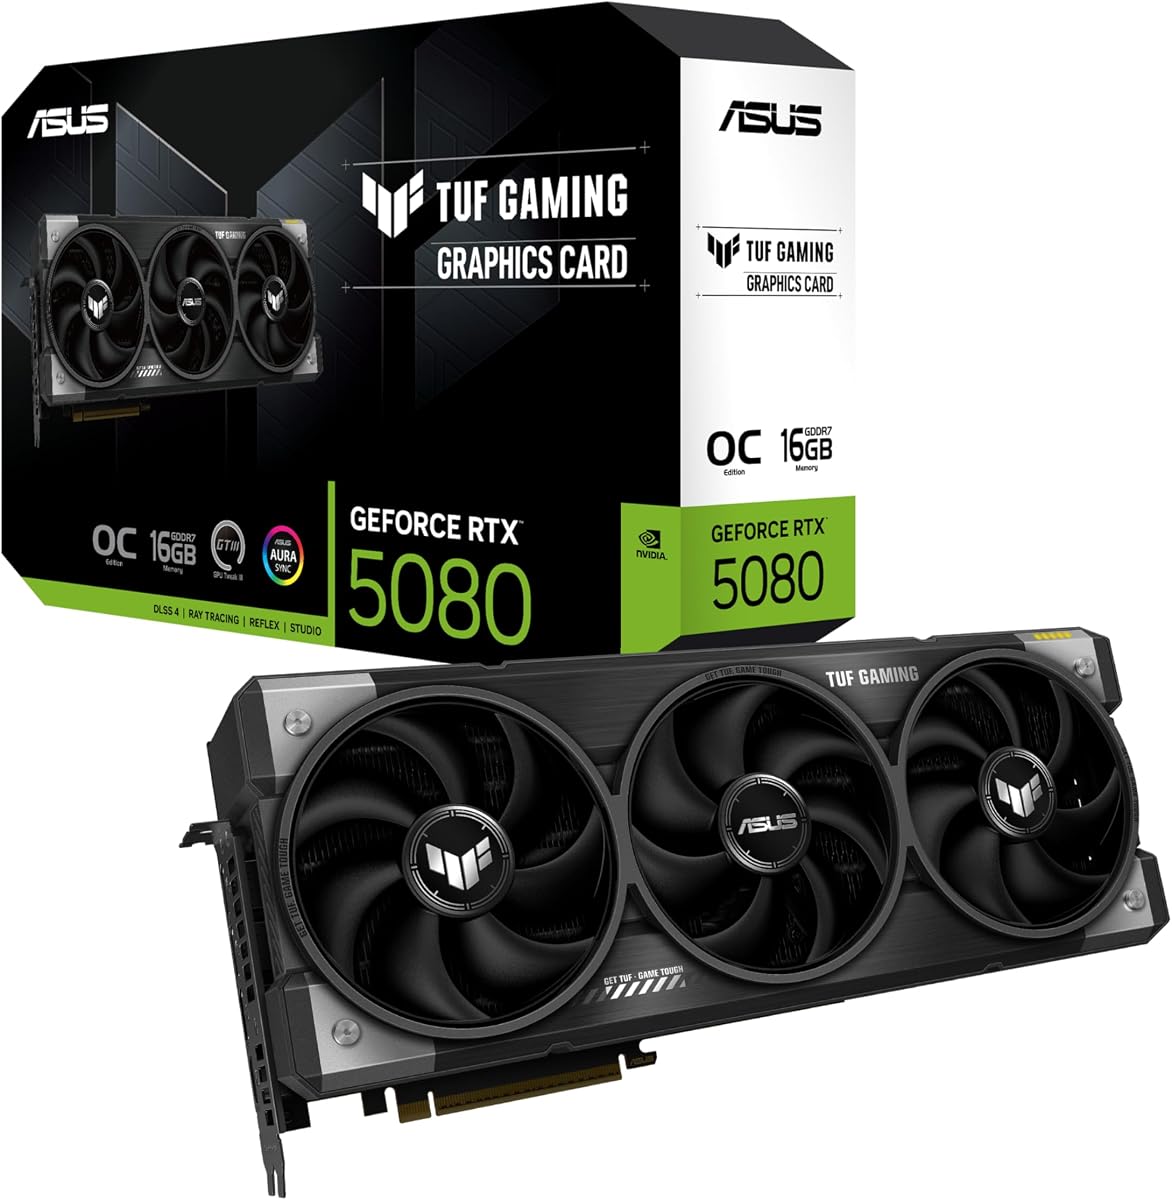
The NVIDIA Blackwell architecture ensures it is ready for the latest AI features and optimizations. Three Axial-tech fans work with a massive fin array to optimize airflow and keep temperatures in check during intensive tasks.
While it requires a powerful power supply and specific connectors the performance and reliability are top notch. Auto-Extreme precision automated manufacturing helps ensure higher reliability which is crucial for unattended training sessions.
Users who need a workstation grade reliability in a consumer form factor will find this TUF model appealing. It combines robust build quality with the raw power needed for heavy AI workloads.
Phase-change pads eliminate air gaps better than paste ensuring consistent cooling performance over the life of the card.
GPU Tweak III software allows you to monitor clock speeds and temperatures in real time for precise control.
We may earn a commission when you buy through this link, at no additional cost to you.
This card is specifically built for running local language models with its focus on local inference and fine-tuning. The turbo blower design is perfect for stacking multiple units to scale up total memory capacity for enterprise needs.
We may earn a commission when you buy through this link, at no additional cost to you.
With thirty-two gigabytes of VRAM it handles large models without offloading which significantly improves latency. The phase-change thermal pads ensure consistent performance even under heavy sustained loads typical of training tasks.
While it carries a premium price the ability to scale across multiple cards in a dense chassis offers flexibility for local clusters. The dual ball fan bearings are rated for longer life than standard designs reducing maintenance needs.
IT professionals setting up dedicated AI servers will appreciate the dense form factor and high memory capacity. It offers a robust solution for organizations that need to keep data and workloads on-premises.
The design supports stacking multiple units to create a private AI cluster without needing rack-mounted servers.
Optimized drivers help utilize the full bandwidth of the memory bus for faster data processing rates.
We may earn a commission when you buy through this link, at no additional cost to you.
This card brings the latest Blackwell architecture to a compact design that fits many small form factor builds. Sixteen gigabytes of fast memory allows for running optimized models locally without hitting VRAM limits immediately.
We may earn a commission when you buy through this link, at no additional cost to you.
The dual BIOS feature lets you toggle between Quiet and Performance profiles giving you control over fan speeds. Axial-tech fans with a smaller hub and barrier ring increase air pressure to cool the card effectively.
Despite its gaming focus the AI performance is strong enough for hobbyist development and inference tasks. The zero decibel technology ensures silence during light loads which is great for home offices.
Users with limited desk space or small cases can still participate in local AI development with this model. It proves that you do not need a massive workstation to start experimenting with large language models.
The slim profile allows for installation in compact cases while still delivering high-end AI capabilities.
Switching BIOS profiles allows you to prioritize silence or speed depending on the time of day.
We may earn a commission when you buy through this link, at no additional cost to you.
This accelerator is designed specifically for high performance computing workloads where reliability is paramount. Its forty-eight gigabytes of memory is sufficient for most large models allowing for complex inference and training tasks.
We may earn a commission when you buy through this link, at no additional cost to you.
The card typically requires a server environment which means it may not fit in a standard consumer desktop. However for data centers or dedicated AI labs it provides the stability needed for continuous operations.
Built with enterprise grade components it can run twenty-four seven without the risk of consumer card failure. The high throughput compute capabilities ensure that you get the most out of your investment over time.
Organizations needing a dedicated accelerator for a shared resource should consider this robust solution. It offers the balance of capacity and performance required for serious industrial or research applications.
Designed for data center use it includes features to ensure long term stability and uptime.
The large VRAM allows for running multiple instances or very large context window models effectively.
We may earn a commission when you buy through this link, at no additional cost to you.
This workstation monster offers ninety-six gigabytes of ECC memory which completely removes VRAM bottlenecks for heavy models. It is engineered for agentic workflows and allows teams to scale intelligence rapidly without cloud latency.
We may earn a commission when you buy through this link, at no additional cost to you.
The Max-Q form factor fits seamlessly into standard desktops while delivering power efficiency and advanced AI performance. With three thousand five hundred one TOPS it accelerates high-performance computing tasks effortlessly.
ECC memory helps prevent data corruption which is critical for long training runs or scientific simulations. The dual-slot design makes it possible to build powerful multi-GPU systems on a desktop or small server.
Researchers and enterprises needing top tier performance will find this card unmatched in its class. It is the ultimate tool for those who require maximum local capability for complex AI development.
ECC memory ensures data integrity which is essential for accurate results in long and complex AI workflows.
High memory bandwidth allows for rapid transfer of large model weights to the processing cores.
We may earn a commission when you buy through this link, at no additional cost to you.
This professional workstation edition is designed for complex engineering and AI workflows. It features ninety-six gigabytes of memory and advanced tensor cores to accelerate model processing and generative tasks.
We may earn a commission when you buy through this link, at no additional cost to you.
The double-flow-through cooling design optimizes airflow to maintain peak performance under high power loads. Universal MIG capabilities allow dividing the GPU into isolated instances for secure multi-user environments.
Compliance with export regulations is required for orders outside the US which adds a layer of scrutiny for international buyers. OEM packaging means it is intended for system integrators rather than individual retail shoppers.
Enterprises requiring secure and isolated environments for AI workloads will appreciate the advanced virtualization features. It represents the pinnacle of workstation graphics hardware for professional scientific and engineering applications.
Dividing the GPU into instances allows multiple users to run tasks securely without interference.
Advanced thermal and core design ensures that high performance is maintained during intensive computation tasks.
We may earn a commission when you buy through this link, at no additional cost to you.
Selecting the right GPU involves balancing memory capacity performance and cost to fit your specific large language model needs.
Memory or VRAM is the most critical factor because it determines how large a model you can load without offloading to system RAM. Larger models require more VRAM to store weights and activations efficiently. If you plan to run models with billions of parameters look for cards with at least sixteen gigabytes or more. Higher capacity allows for larger context windows and better performance during training.
Prioritize cards with larger memory pools if you want to run state-of-the-art models locally.
The type of memory such as GDDR6 or GDDR7 affects how quickly data moves between the GPU and its cores. Faster memory reduces latency during inference and speeds up data processing. Newer cards often use GDDR7 which provides higher bandwidth than previous generations. This is especially important for large models that require constant data streaming.
Choose the latest memory technology available to ensure faster data throughput and better overall responsiveness.
The underlying architecture defines the AI-specific features and efficiency of the card. Newer generations include dedicated tensor cores or accelerators that significantly improve AI performance. Look for models based on recent architectures like Blackwell or RDNA 4 which have specialized hardware for machine learning. Older cards may struggle with complex AI workloads compared to newer ones.
Opt for the latest architecture to get the best AI acceleration and future-proof your investment.
Effective cooling is essential because AI tasks often push the GPU to high utilization for long periods. Cards with robust cooling systems like WINDFORCE or blower designs prevent thermal throttling and noise. A good thermal solution ensures the card maintains peak performance throughout long training sessions. Consider the physical design to ensure it fits your case and airflow needs.
Look for cards with proven thermal solutions to maintain consistent performance during heavy loads.
High-performance GPUs require significant power and may need specific connectors like 12VHPWR. Check your power supply capacity and connectors before buying to ensure stable operation. Inefficient power delivery can lead to system instability or crashes during intensive tasks. Ensure your system can handle the thermal and electrical demands of the card.
Verify your power supply and case compatibility to avoid installation issues and system instability.
Software ecosystem matters for compatibility with frameworks like PyTorch and TensorFlow. Some cards have better driver support and community resources than others. Professional cards often come with optimized drivers for stability in production environments. Ensure the card you choose has strong software support for the tools you intend to use.
Confirm that the card has strong software support for the frameworks and tools you plan to use.
The physical size of the card determines if it fits in your case or server chassis. Some workstation cards have blower designs that are easier to stack in multi-GPU setups. Ensure there is enough physical space for the card and its cooling system. Compact designs are better for smaller builds while larger cards offer better cooling.
Check the physical dimensions to ensure the card fits in your specific build or server rack.
If you plan to add more cards later check if the system supports scaling across multiple units. Some cards are optimized for multi-GPU deployments which increases total memory and compute power. This is useful for teams needing to run multiple models or larger contexts. Ensure your motherboard and power supply support the number of cards you want.
Choose cards that support multi-GPU scaling if you plan to expand your setup in the future.
Ensure your power supply is rated sufficiently for the GPU and that all cables are securely connected. Use high-quality power cables to prevent voltage drops that can cause instability during intensive tasks.
Install the latest drivers from the manufacturer to get the best performance and security updates. Keep your software frameworks up to date to take advantage of new optimizations and features.
Monitor temperatures using built-in tools or third-party apps to ensure the card stays within safe limits. Clean dust filters regularly to maintain airflow and prevent overheating during long operations.
You need at least sixteen gigabytes of VRAM to run smaller models comfortably. For larger models with billions of parameters twenty-four gigabytes or more is recommended. Cards with thirty-two or ninety-six gigabytes allow for running the largest models without offloading.
NVIDIA currently has a larger ecosystem with better driver support for AI frameworks like PyTorch and TensorFlow. AMD has made progress with newer architecture but software support is still catching up in some areas.
Not necessarily for hobbyist or small team use. Consumer cards with high memory capacity can handle many tasks. Workstation cards offer ECC memory and stability benefits for critical professional workloads.
Yes many modern gaming cards have sufficient memory and compute power for training smaller models. However they may not have the same stability or software support as professional cards for long sessions.
GDDR7 offers higher bandwidth than GDDR6 allowing for faster data transfer rates. This is crucial for AI workloads that require moving large amounts of data quickly between memory and cores.
You can use manufacturer software like GPU Tweak or third-party tools like HWMonitor. These tools show real-time temperature and clock speeds so you can ensure the card is not throttling.
Yes but check your power supply and case size before installing a new card. Multi-GPU support allows you to add more cards later to increase total memory and performance.
ECC memory corrects data errors on the fly which prevents corruption during long training sessions. This is critical for scientific and professional workloads where accuracy is paramount.
We have reviewed ten top options ranging from budget-friendly consumer models to powerful professional workstation cards. Each choice offers distinct advantages depending on your specific needs and budget constraints.
Prioritize memory capacity and architecture generation to ensure your system can handle the models you want to run. Consider cooling and power requirements to maintain stability during long workloads.
Check current availability and ensure your system is compatible before making a purchase decision. Technology evolves quickly so always verify the latest details before finalizing your build.